Bots & rules
one policy per intent.
Policies per intent with per-bot exceptions and rate limits, the verification sources, server and cache rule snippets, and the full built-in bot list.
01Policies
CryptoMeter → Bots & rules has three sections: Policies, Verification sources and Server & cache rules.
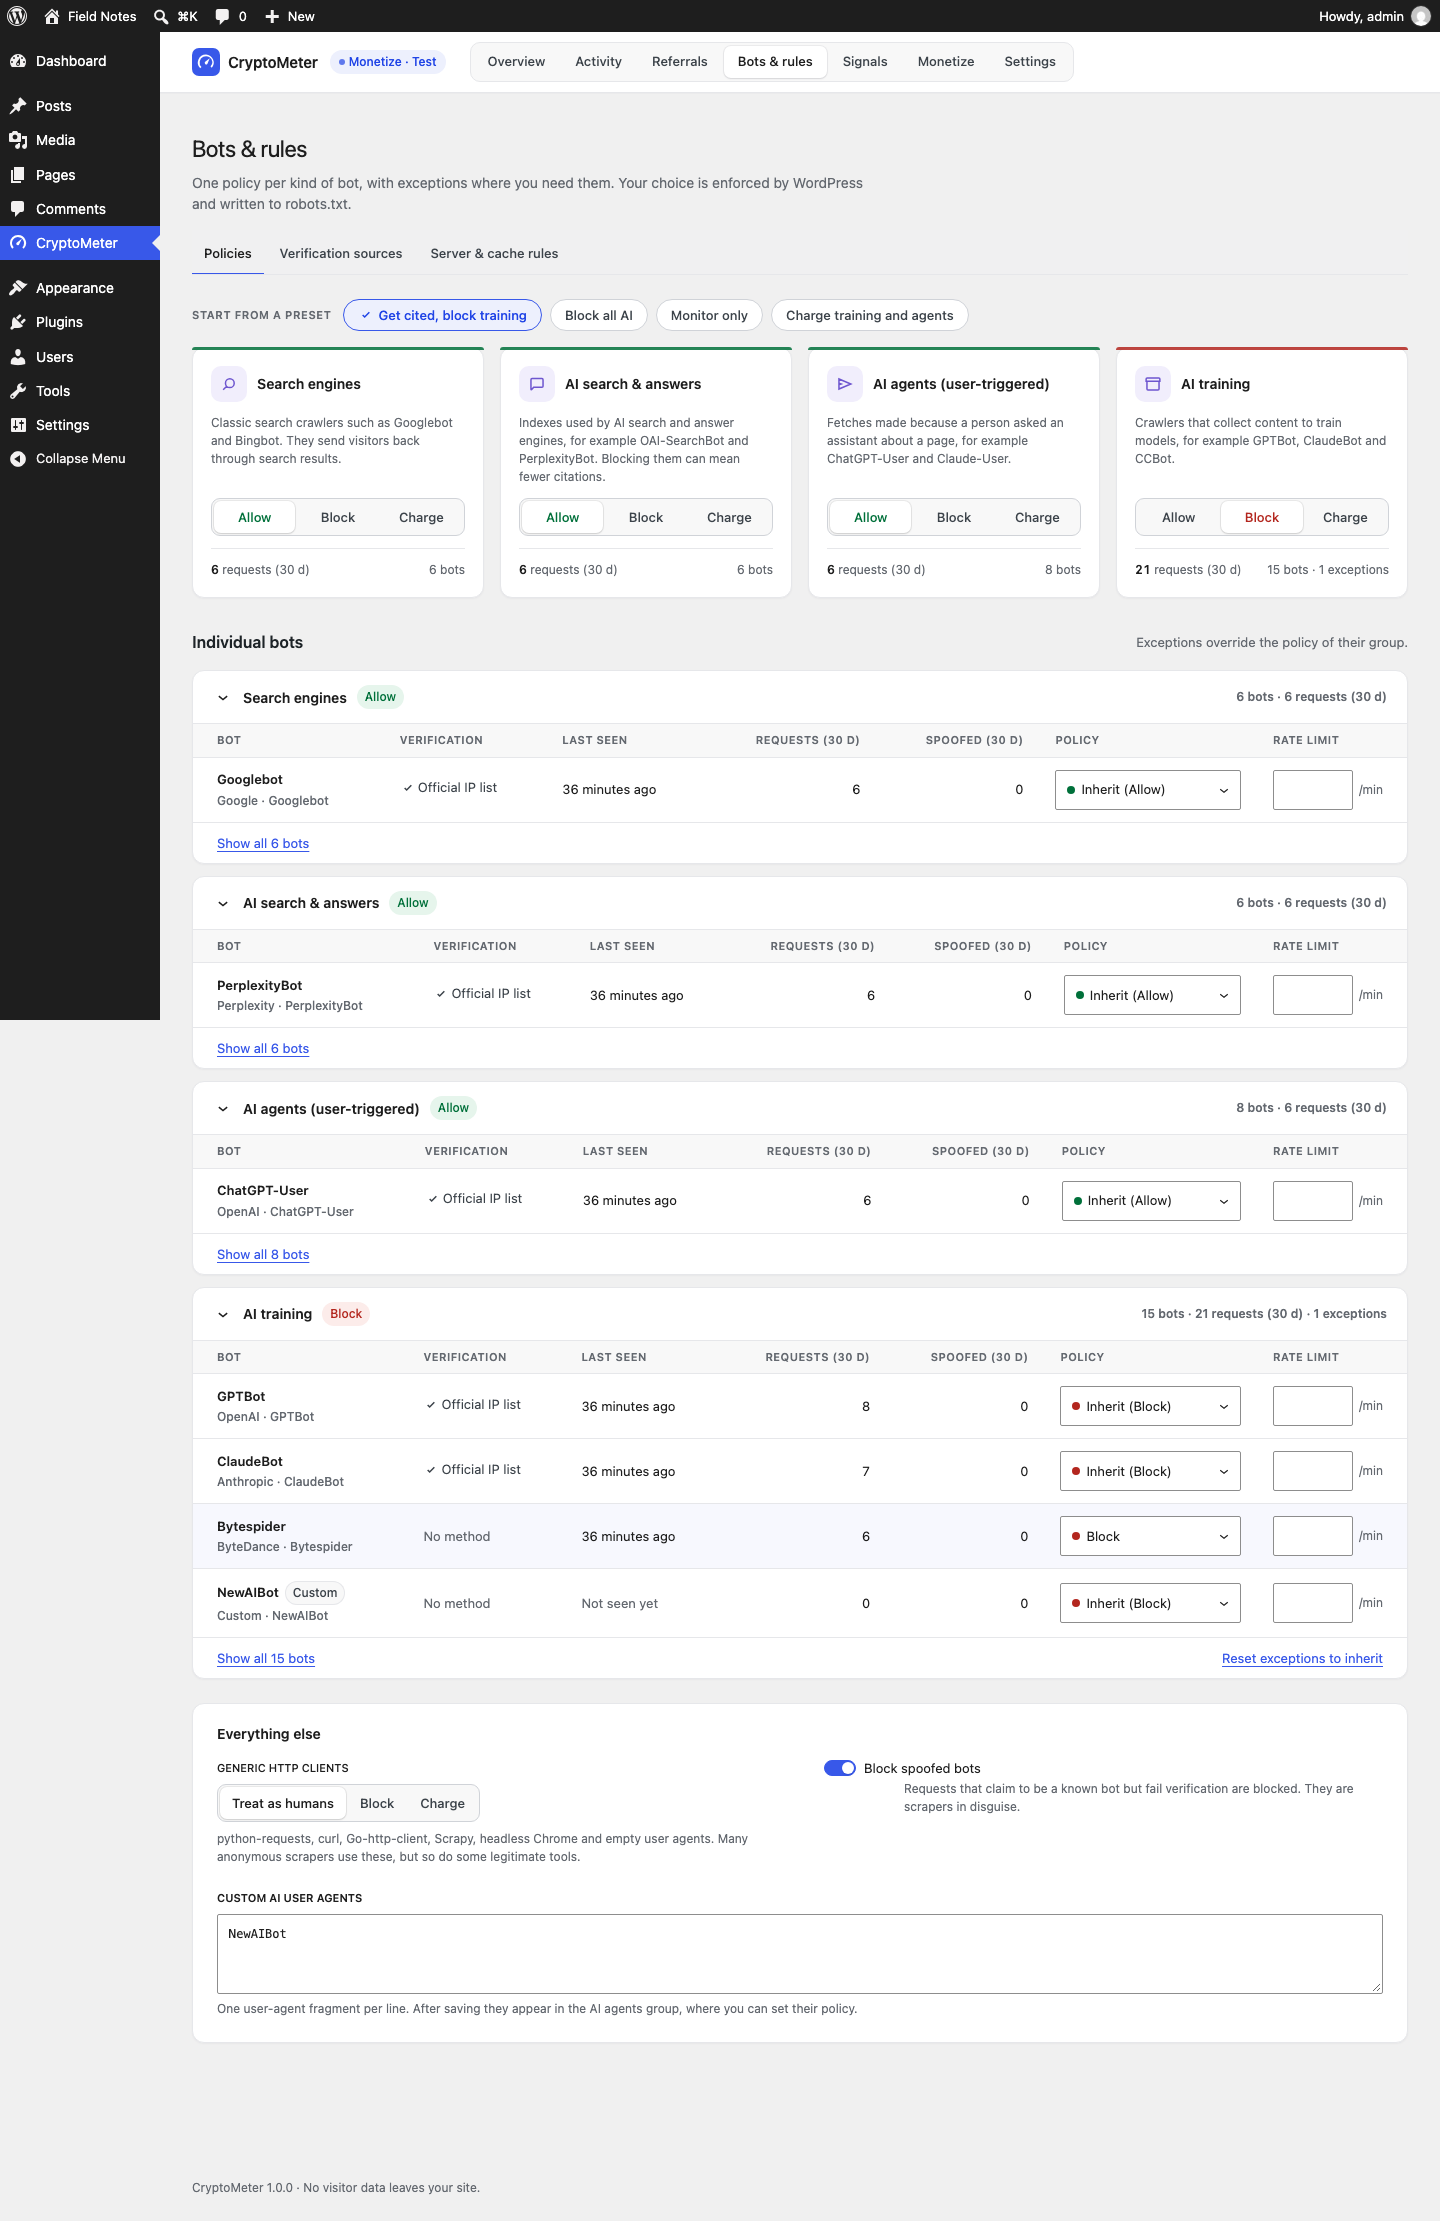
- Start from a preset: the four presets from section 5. A confirmation dialog explains what is replaced.
- Intent cards: one per intent (Search engines, AI search & answers, AI agents (user-triggered), AI training) with Allow / Block / Charge, requests in the last 30 days, number of bots and exceptions.
- Charge is locked until Monetize is on. A stored Charge policy acts as Allow while Monetize is off ("Charge acts as Allow until Monetize is on.").
- Blocking search engines shows "This removes your site from search results."
- Blocking AI search & answers can mean fewer citations in AI search tools.
- Individual bots: one table per intent with Verification method, Last seen, Requests (30 d), Spoofed (30 d), Policy (Inherit (…), Allow, Block, Charge) and Rate limit (requests per minute; empty or 0 = no limit). Reset exceptions to inherit removes the group's exceptions.
- Everything else:
- Generic HTTP clients: Treat as humans (default), Block or Charge. Covers python-requests, curl, Go-http-client, Scrapy, headless Chrome, empty user agents and similar libraries. Many anonymous scrapers use these, but so do some legitimate tools (uptime monitors, feed readers).
- Block spoofed bots (default on): requests that claim to be a known bot but fail verification are blocked.
- Custom AI user agents: one user-agent fragment per line (at least 3 characters). After saving they appear in the AI training group, where you can set their policy.
Press Save changes in the bar at the bottom. "Bot policies saved. robots.txt and signals are updated." confirms it.
Per-bot rate limits
A per-bot limit counts all requests of that bot per minute, across all its IP addresses. Above the limit the bot gets HTTP 429 with Retry-After: 60 and the text "Too many requests from this crawler. Slow down." It applies on every page, whatever the bot's policy. Verified on a test install: with a limit of 3, requests 4 and 5 in the same minute returned 429.
Command palette
Where WordPress provides its command palette (Ctrl/⌘ + K), the CryptoMeter page adds commands such as "CryptoMeter: Overview", "CryptoMeter: Bots & rules", "CryptoMeter: Settings" and "CryptoMeter: Block AI training bots".
02Verification sources
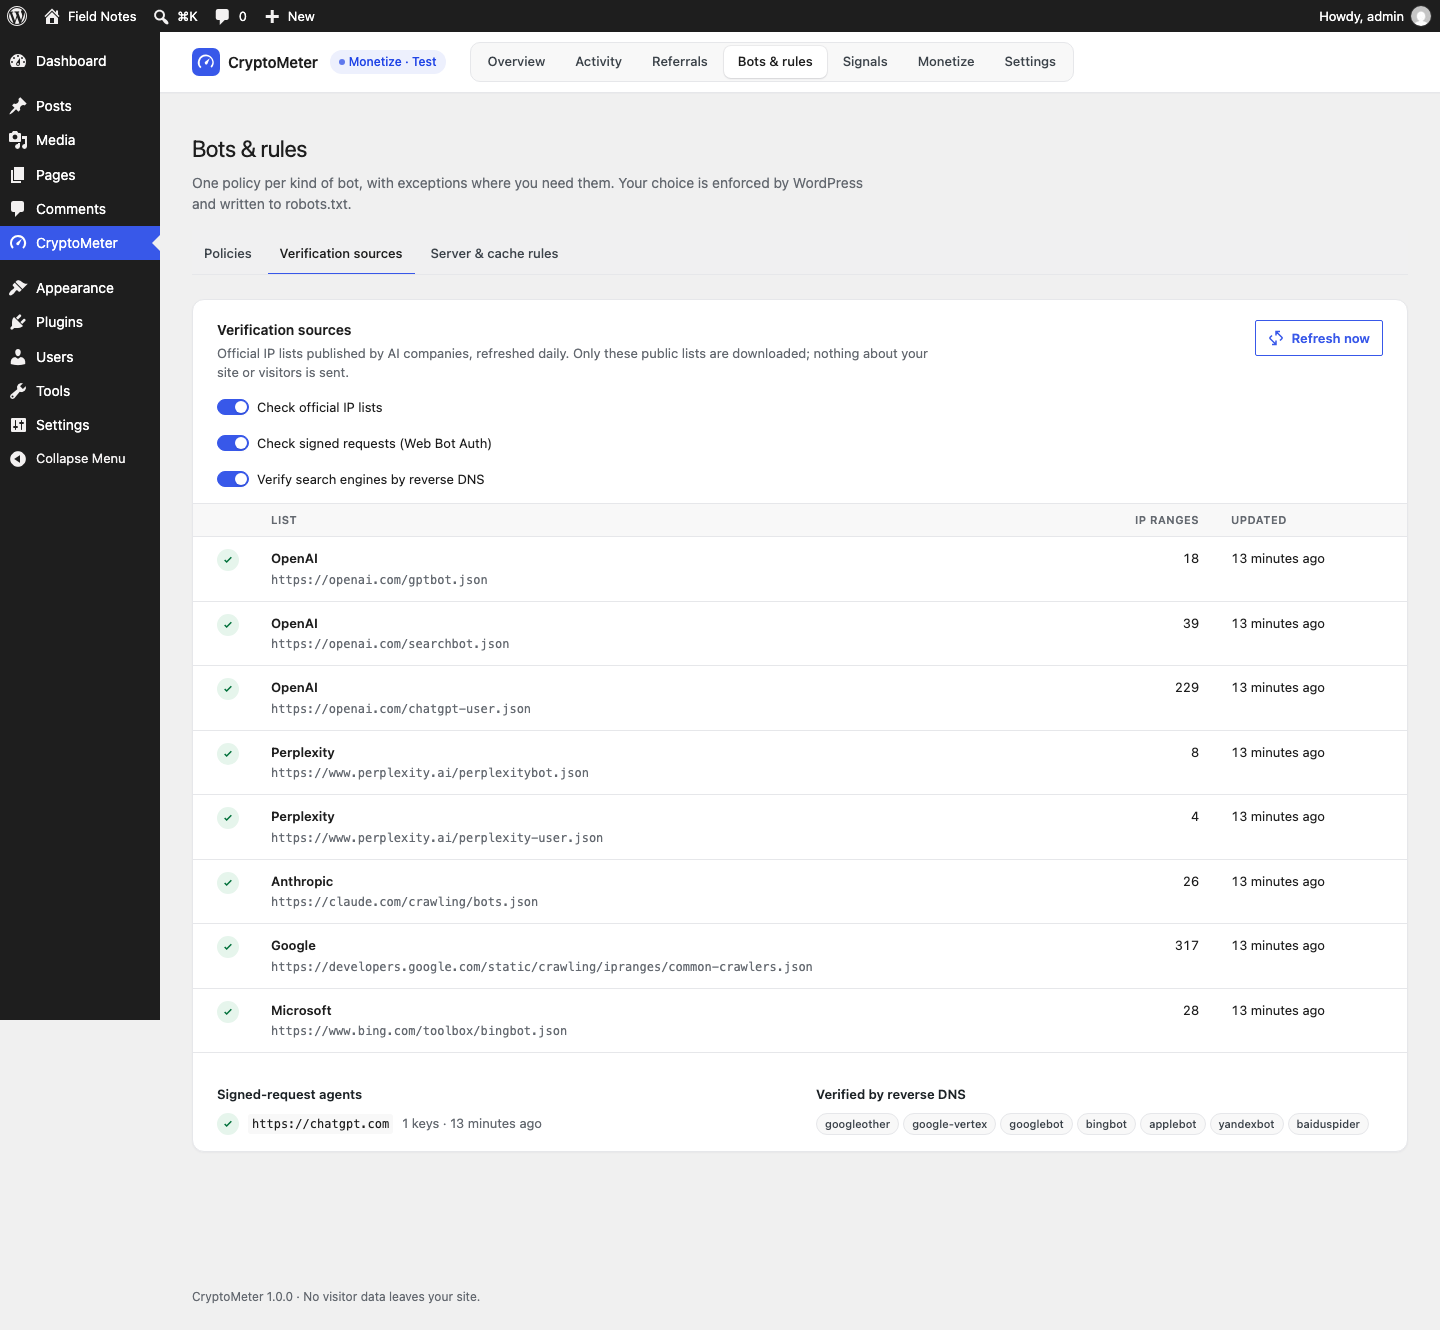
- Check official IP lists, Check signed requests (Web Bot Auth) and Verify search engines by reverse DNS switch each method on or off (all on by default).
- The table shows each list's vendor and URL, the number of IP ranges and when it was last updated. A red dot shows the fetch error; the last good copy is kept.
- Refresh now downloads all lists and the key directory immediately. Otherwise they refresh once a day by WP-Cron.
- Signed-request agents: origins whose Web Bot Auth keys are trusted (default
https://chatgpt.com), with key count and age. - Verified by reverse DNS: googleother, google-vertex, googlebot, bingbot, applebot, yandexbot, baiduspider.
How verdicts are decided is explained in section 14.
03Server & cache rules
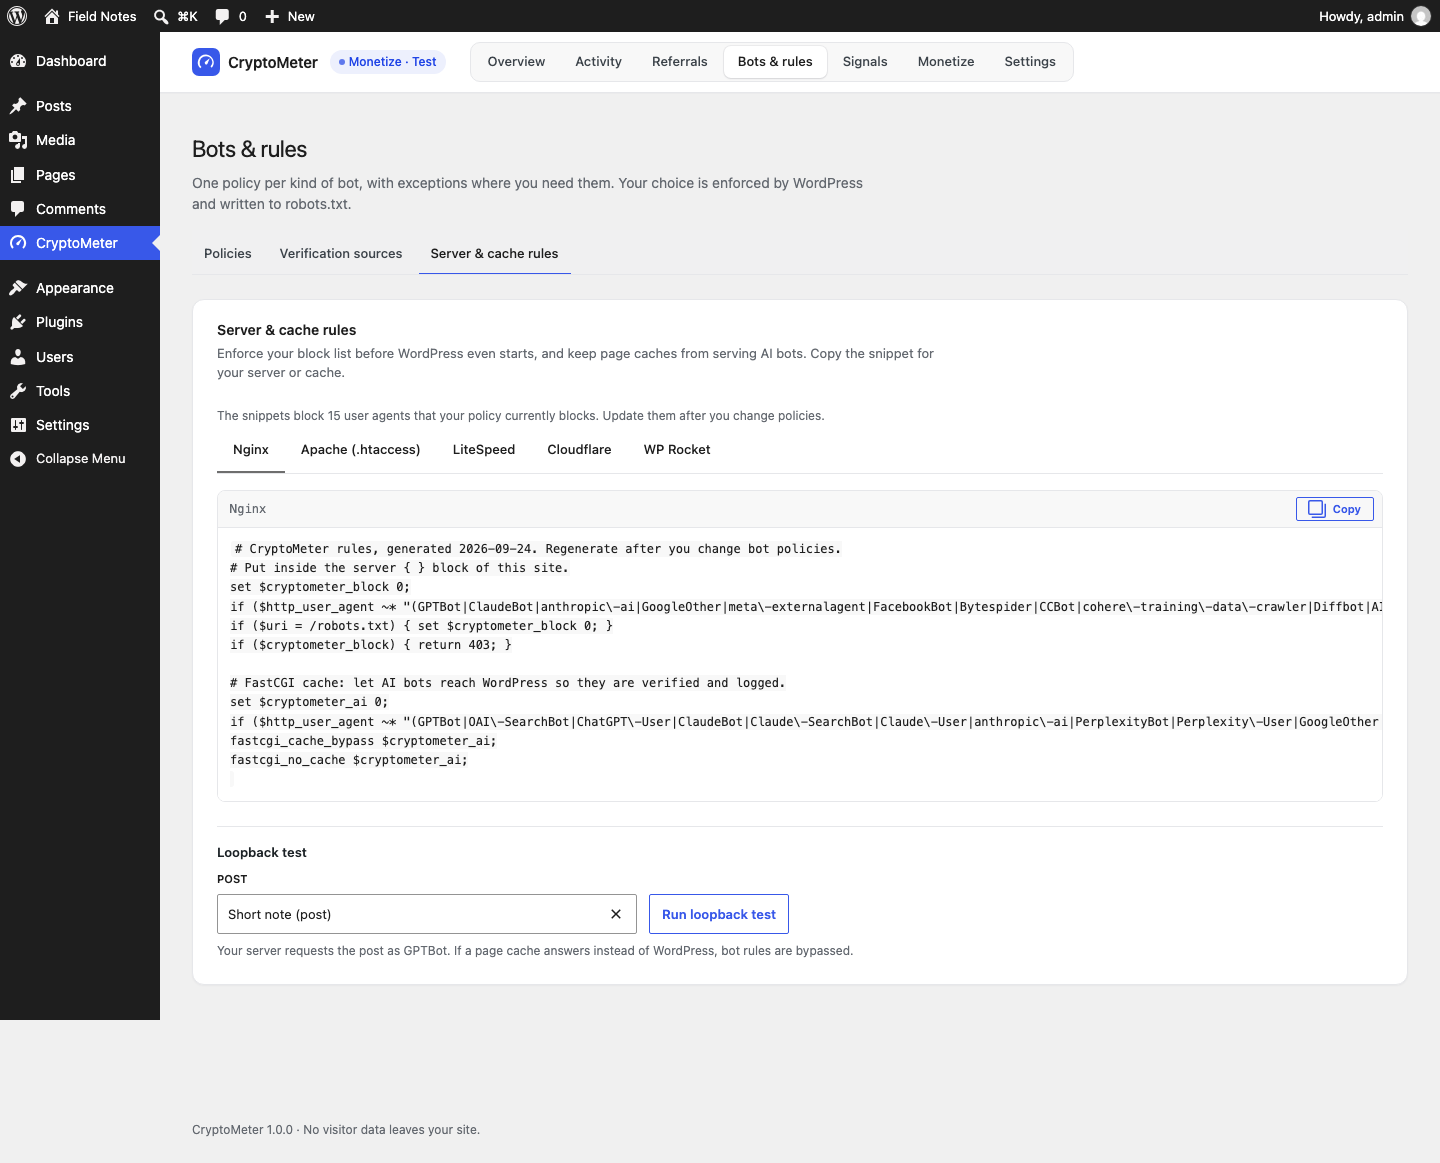
CryptoMeter's own blocking happens inside WordPress. Blocking at the web server or CDN saves PHP work, and excluding AI bots from page caches lets CryptoMeter see, verify and log them. The snippets are regenerated each time you open the tab ("Update them after you change policies").
| Tab | What it contains | Where it goes |
|---|---|---|
| Nginx | Returns 403 for blocked user agents (except /robots.txt) and sets fastcgi_cache_bypass / fastcgi_no_cache for all AI user agents. | Inside the server { } block of the site; then reload Nginx. |
| Apache (.htaccess) | mod_rewrite rule answering 403 ([F]) for blocked user agents, except /robots.txt. | .htaccess, above # BEGIN WordPress. |
| LiteSpeed | The Apache rule plus a LiteSpeed Cache no-cache rule for AI user agents. | .htaccess, above # BEGIN WordPress. |
| Cloudflare | A WAF custom rule expression matching blocked user agents, excluding /robots.txt. | Cloudflare dashboard → Security → WAF → Custom rules: paste as the expression, action Block. |
| WP Rocket | All AI user-agent fragments, one per line. | WP Rocket → Advanced Rules → "Never Cache User Agent(s)". |
A mistake in server configuration can take a site down. Keep a backup of the file you edit, and test with the curl commands from the Quick start. Server-level rules block by user agent only (no verification), and requests stopped there never reach WordPress, so they do not appear in Activity. The snippets were generated and read on a test install; MIKODES has not run them on a live Nginx, Apache, LiteSpeed or Cloudflare setup.
The Loopback test at the bottom is explained in Simulator and loopback test and Page caches.
04Built-in bot list
A bot is recognised when its match fragment appears in the request's User-Agent (case-insensitive). ChatGPT agent uses a normal Chrome user agent and is recognised only by its Web Bot Auth signature. Listing a company here only means CryptoMeter recognises its crawler; it says nothing about whether it pays through x402.
| Bot | Company | Intent | Match | Verification |
|---|---|---|---|---|
| GPTBot | OpenAI | AI training | GPTBot | Official IP list |
| OAI-SearchBot | OpenAI | AI search & answers | OAI-SearchBot | Official IP list |
| ChatGPT-User | OpenAI | AI agents | ChatGPT-User | Official IP list, signature |
| ChatGPT agent | OpenAI | AI agents | (signature only) | Signed request |
| ClaudeBot | Anthropic | AI training | ClaudeBot | Official IP list |
| Claude-SearchBot | Anthropic | AI search & answers | Claude-SearchBot | Official IP list |
| Claude-User | Anthropic | AI agents | Claude-User | Official IP list |
| anthropic-ai | Anthropic | AI training | anthropic-ai | Official IP list |
| PerplexityBot | Perplexity | AI search & answers | PerplexityBot | Official IP list |
| Perplexity-User | Perplexity | AI agents | Perplexity-User | Official IP list |
| GoogleOther | AI training | GoogleOther | Official IP list, reverse DNS | |
| Google-CloudVertexBot | AI agents | Google-CloudVertexBot | Official IP list, reverse DNS | |
| Meta-ExternalAgent | Meta | AI training | meta-externalagent | No method |
| Meta-ExternalFetcher | Meta | AI agents | meta-externalfetcher | No method |
| FacebookBot | Meta | AI training | FacebookBot | No method |
| Amazonbot | Amazon | AI search & answers | Amazonbot | No method |
| Bytespider | ByteDance | AI training | Bytespider | No method |
| CCBot | Common Crawl | AI training | CCBot | No method |
| cohere-ai | Cohere | AI agents | cohere-ai | No method |
| cohere-training-data-crawler | Cohere | AI training | cohere-training-data-crawler | No method |
| MistralAI-User | Mistral | AI agents | MistralAI-User | No method |
| DuckAssistBot | DuckDuckGo | AI search & answers | DuckAssistBot | No method |
| YouBot | You.com | AI search & answers | YouBot | No method |
| Diffbot | Diffbot | AI training | Diffbot | No method |
| AI2Bot | Allen Institute | AI training | AI2Bot | No method |
| Timpibot | Timpi | AI training | Timpibot | No method |
| omgili | Webz.io | AI training | omgili | No method |
| ImagesiftBot | Hive | AI training | ImagesiftBot | No method |
| Googlebot | Search engines | Googlebot | Official IP list, reverse DNS | |
| Bingbot | Microsoft | Search engines | bingbot | Official IP list, reverse DNS |
| Applebot | Apple | Search engines | Applebot | Reverse DNS |
| DuckDuckBot | DuckDuckGo | Search engines | DuckDuckBot | No method |
| YandexBot | Yandex | Search engines | YandexBot | Reverse DNS |
| Baiduspider | Baidu | Search engines | Baiduspider | Reverse DNS |
That is 28 AI crawlers and agents and 6 search engines, plus your custom user agents. A request that carries an x402 payment or access-pass header but matches no known bot is recorded as "x402 client".