Signals
say what AI may do.
robots.txt Content-Signal, IETF Content-Usage, RSL, TDMRep and noai tags from one screen, with a preview of exactly what is published. Signals are requests, not locks; Bots & rules enforces them.
01What may AI do with your content?
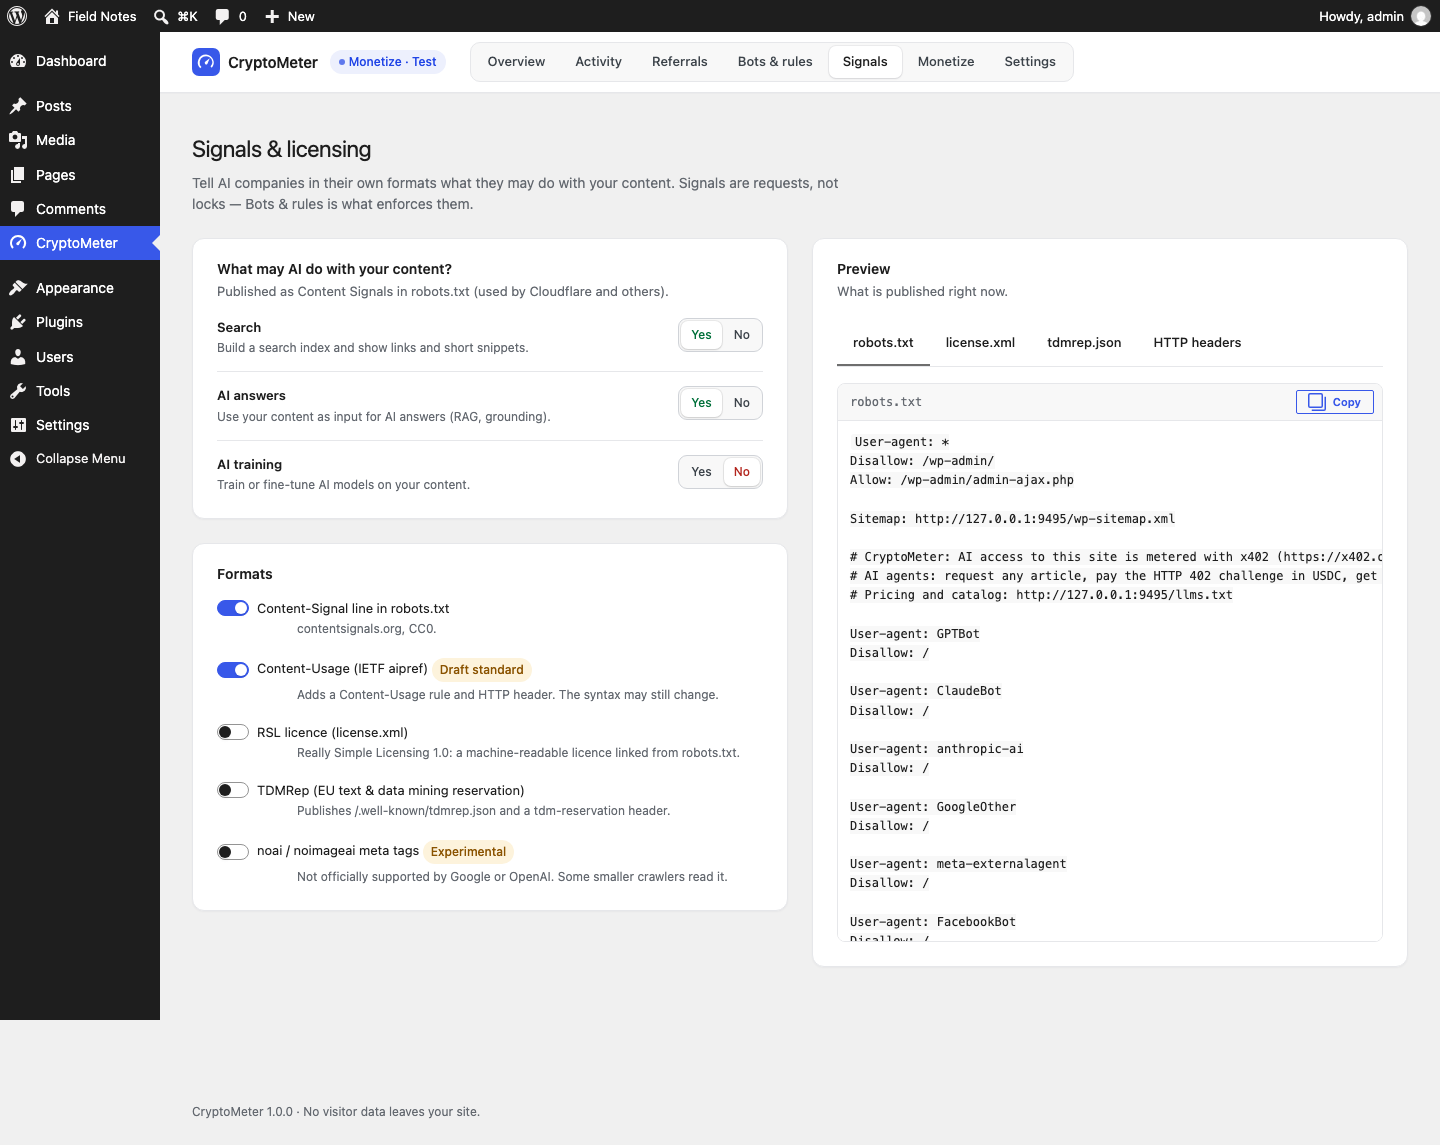
CryptoMeter → Signals ("Signals & licensing") tells AI companies, in their own formats, what they may do with your content. As the screen says: signals are requests, not locks; Bots & rules is what enforces them.
| Choice | Meaning | Default |
|---|---|---|
| Search | Build a search index and show links and short snippets. | Yes |
| AI answers | Use your content as input for AI answers (RAG, grounding). | Yes |
| AI training | Train or fine-tune AI models on your content. | No |
02Formats
| Toggle | What is published | Default |
|---|---|---|
| Content-Signal line in robots.txt | A User-agent: * group in the virtual robots.txt with Content-Signal: search=yes, ai-input=yes, ai-train=no (contentsignals.org, CC0). | On |
| Content-Usage (IETF aipref) Draft standard | Content-Usage: train-ai=n, ai-use=y, search=y in the same robots.txt group and as an HTTP response header on front-end pages. The IETF syntax is a draft and may still change. | On |
| RSL licence (license.xml) | An RSL 1.0 document at /license.xml, a License: line at the top of robots.txt and a Link: <…/license.xml>; rel="license"; type="application/rsl+xml" header. Extra fields: Licence terms and Licensing contact (e-mail or URL, optional). | Off |
| TDMRep (EU text & data mining reservation) | /.well-known/tdmrep.json, a tdm-reservation: 1 header and meta tag, and optionally a TDM policy URL (tdm-policy). | Off |
| noai / noimageai meta tags Experimental | <meta name="robots" content="noai, noimageai"> and an X-Robots-Tag: noai, noimageai header. Not officially supported by Google or OpenAI; some smaller crawlers read it. | Off |
RSL licence terms
- Search and AI answers allowed, AI training prohibited (default)
- All AI use prohibited (search indexing allowed)
- Follow the search / AI answers / AI training choices above
- Free reuse with attribution and a link
- AI use needs a licence: contact me
- Pay per crawl with x402 (Monetize): only offered while Monetize is on; if Monetize is off or not set up, the default terms are published instead.
Output verified on a test install with RSL on and a contact address:
<?xml version="1.0" encoding="UTF-8"?>
<rsl xmlns="https://rslstandard.org/rsl">
  <content url="/">
    <license>
      <prohibits type="usage">ai-train</prohibits>
      <legal type="contact">mailto:licensing@example.com</legal>
    </license>
  </content>
</rsl>
The Preview (tabs robots.txt, license.xml, tdmrep.json, HTTP headers) updates as you change options ("Unsaved — this is what will be published after you save."). Press Save changes; "Signals saved and published." confirms it.
If a real robots.txt file exists in your web root, the web server serves it and WordPress's virtual robots.txt (with CryptoMeter's lines) is never used. The preview then shows your physical file. Either delete the file or copy the lines into it by hand.
robots.txt, /license.xml and /.well-known/tdmrep.json stay readable for every bot, including blocked ones. Signal lines, headers and files are only published while CryptoMeter is switched on (Settings → General).